The Wider Index
The Epstein files are bigger than any one copy of them. This page catalogs every open corpus of OCR'd Epstein-files text we could find — community mirrors, institutional releases, and our own OCR — and rates each one on three axes. The chart grid and table below recompute from whatever you filter; click a row for detail.
The known universe: 1,394,531 DOJ documents (~2,770,154 pages, EFTA-numbered per page), the two House Oversight estate releases (31,621 pages), 11,830 court records, and 16 BOP videos. This catalog tracks 37 sources and records 9 dead or vaporware leads so the next person does not chase them again.
| Preview | Source | Covers | Docs ▼ | Engine | License | F·C·U | Seen | Status |
|---|---|---|---|---|---|---|---|---|
no shot | Epstein-Files (embedded-text) ↗ Nikityyy (HF) | DS1DS2DS3DS4DS5+10 | 4.1M | Native text pypdfium2 embedded-text extraction — not OCR; scans yield nothing | Permissive | 2 / 3 / 3 | — | live |
no shot | SOTA OCR extract (DS1-12) ↗ Daniel Voyce (certant.ai) | DS1DS2DS3DS4DS5+7 | — | Undisclosed undisclosed 'SOTA' system; '64 x 3090 GPUs' claimed | None stated | 3 / 4 / 2 | — | fragile |
 | Epstein-Pipeline / epsteinexposed.com ↗ stonesalltheway1 | DS1DS2DS3DS4DS5+11 | 2.1M | Open VLM Not named. OCR appears only in paid-tier marketing ("Enhanced exports with OCR & cross-references", "$99 Full Dataset (OCR snippets ...)"). | Terms-gated | 4 / 5 / 3 | — | live |
 | Epstein-research-data / epstein-data.com ↗ rhowardstone (solo) | DS1DS2DS3DS4DS5+11 | 1.4M | Classic OCR Not named ('OCR-extracted text' offered without engine credit). | CC-BY-NC | 3 / 5 / 5 | — | live |
 | epstein-data ↗ kabasshouse (HF); frontend epstein.academy | DS1DS2DS3DS4DS5+9 | 1.4M | Mixed Gemini 2.5 Flash Lite (856,028 files) + Tesseract (531,279, mostly DS9); per-file engine attribution | CC-BY | 4 / 5 / 4 | — | live |
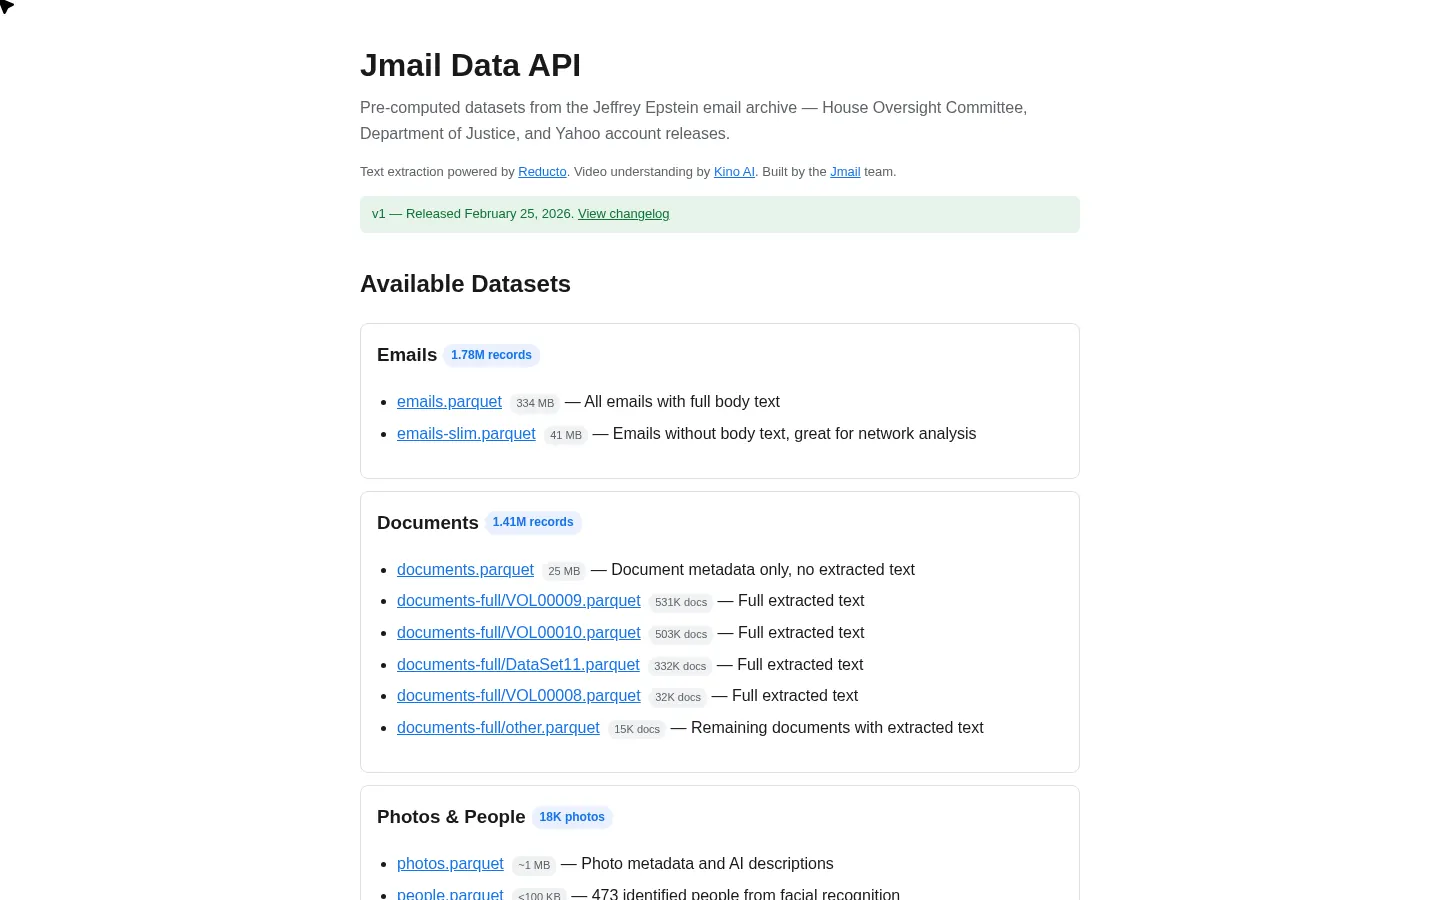 | Jmail open data ↗ Jmail team (lukeigel et al.) | DS8DS9DS10DS11Emails+1 | 1.4M | Commercial VLM Reducto (commercial document-parse AI); video by Kino AI | Public domain / CC0 | 5 / 4 / 5 | 2026-02-24 | live |
no shot | DOJ Epstein Library ↗ US Department of Justice | DS1DS2DS3DS4DS5+11 | 1.4M | Mixed mixed: natives + DOJ-side OCR (unproven) | Public domain / CC0 | 3 / 5 / 2 | 2025-12-01 | live |
 | tommycarstensen.com/epstein (JSONL text) ↗ Tommy Carstensen | DS1DS2DS3DS4DS5+11 | 1.4M | Undisclosed undisclosed (pdf_text extraction) | None stated | 3 / 5 / 4 | — | live |
no shot | epstein-files-ocr-complete ↗ ishumilin (HF) | DS1DS2DS3DS4DS5+7 | 1.4M | Undisclosed Proprietary automated OCR pipeline by Wild Ma-Gässli (wildma.ch) | Public domain / CC0 | 4 / 5 / 5 | 2026-03-19 | live |
no shot | PlainSite USDOJ-EFTA collection ↗ Think Computer Corp | DS1DS2DS3DS4DS5+7 | 1.3M | No OCR none (explicitly) | Terms-gated | 1 / 4 / 3 | — | live |
no shot | epstein-doj-document-index ↗ LayerDynamics (HF) | DS1DS2DS3DS4DS5+7 | 550k | No OCR — | None stated | · / 3 / 3 | — | live |
 | epstein.dugganusa.com ↗ DugganUSA | DS1DS2DS3DS4DS5+7 | 400k | Undisclosed Not mentioned. | None stated | 2 / 2 / 2 | — | live |
 | CourtListener / RECAP ↗ Free Law Project (501c3) | Court | 111k | Mixed Tesseract (documented since 2012) + natives | Permissive | 4 / 3 / 3 | — | live |
no shot | This site (marker OCR) ↗ epstein-index (us) | DS1DS2DS3DS4DS6+12 | 46.6k | Mixed marker-pdf 1.5.5 + surya-ocr 0.12.1 for the 14,961 DOJ/FOIA documents; the 31,621 estate-release pages serve the ep-nov-12 mirror's OCR text (engine undisclosed) | Public domain / CC0 | · / 2 / 4 | — | live |
 | epstein-files.org ↗ Andrew Walsh ('tsardoz', Sifter Labs) | DS1DS2DS3DS4DS5+7 | 33.9k | Undisclosed AI (unnamed) | None stated | 3 / 2 / 1 | — | vapor |
no shot | ep-nov-12.greg.technology ↗ Greg Sadetsky | House OctHouse Nov | 31.6k | Undisclosed No OCR engine found named anywhere (Kagi forum/web lenses, HN). Closest HN neighbor project (epsteinsphone.org by HN user toon-noot, repo github.com/Toon-nooT/epsteins-phone-reconstructed) says only: "I used an OCR + vision-LLM pipeline to extract individual messages from the email screenshots" — a different project, often confused with this one. | None stated | 3 / 2 / 2 | — | degraded |
no shot | House Oversight official containers ↗ House Oversight Committee | House OctHouse Nov | 31.6k | Native text estate natives + extracted text (not OCR) | Public domain / CC0 | 5 / 3 / 3 | 2025-10-17 | live |
no shot | jmail-* annotated family ↗ 567 Labs (HF) | EmailsDS8DS9DS10DS11+1 | 28.0k | Commercial VLM Reducto (via jmail) + LLM annotations (severity, relevance, description) | None stated | 4 / 1 / 4 | — | live |
no shot | DocumentCloud (MuckRock) ↗ MuckRock /-TMU | Grand juryCourt | 27.2k | Classic OCR DocumentCloud OCR (Tesseract family) | CC-BY | 3 / 2 / 4 | — | live |
no shot | epstein-files-20k ↗ teyler (HF); reuploads rbinrs, aurora2424, nglif | House Nov | 25.0k | Classic OCR Tesseract | None stated | 2 / 2 / 4 | — | live |
no shot | epstein-ranker-dataset ↗ linogova (Kaggle) | House Nov | 25.0k | Undisclosed locally-run AI (unspecified) | None stated | 2 / 1 / 3 | — | live |
no shot | Estate Release 7 OCR'd PDFs ↗ civicanger.com ('Default Account') | House Nov | 20.0k | Undisclosed undisclosed ('OCR isn't 100% accurate') | None stated | 2 / 1 / 2 | 2025-11-15 | live |
no shot | Epstein_case_leaked_OCR_results ↗ LovenSar (HF) | DS1DS2DS3DS4DS5+7 | 11.9k | Open VLM Local LLM: glm-ocr via Ollama + qwen3.5 router | None stated | 3 / 1 / 2 | — | removed |
no shot | FULL_EPSTEIN_INDEX ↗ theelderemo; mirrors genevera, B00MEMBERX | House NovDS1FBI VaultBOP video | 10.0k | Undisclosed unnamed ('OCR made mistakes') | Permissive | 2 / 2 / 4 | — | live |
no shot | epstein-images (FBI scans) ↗ nynxz (HF) | FBI Vault | 8.4k | No OCR — | None stated | · / 1 / 3 | — | live |
no shot | epstein-fbi-files ↗ svetfm (HF) | FBI Vault | 8.2k | Commercial OCR AWS Textract with per-record ocr_confidence | CC-BY | 5 / 1 / 4 | — | live |
no shot | Pinpoint EFTA collection ↗ Brian Allen (private Google account) | DS1DS2DS3DS4DS5+7 | 7.5k | Commercial OCR Google OCR/NLP | Terms-gated | 4 / 1 / 2 | — | live |
no shot | LLM-structured email sets ↗ notesbymuneeb / Hannah2704 / pupepps; KillerShoaib; bru02 (HF) | Emails | 5.1k | Open VLM LLM structuring over released emails (incl. jmail re-scrape) | None stated | 3 / 1 / 3 | — | live |
no shot | COURIER Pinpoint collection (NOV 12) ↗ Camaron Stevenson, COURIER | House Nov | 2.9k | Commercial OCR Google Pinpoint | Terms-gated | 3 / 1 / 2 | — | live |
no shot | EpsteinFiles ↗ Mark Ramm | House Oct | 2.9k | Undisclosed OCR pipeline included (ocr_documents.py) | Permissive | 2 / 1 / 4 | 2025-11-14 | live |
 | epstein-docs.github.io ↗ epstein-docs org | DS1FBI Vault | 400 | Open VLM OpenAI-compatible vision model returning text + entities | Permissive | 3 / 0 / 3 | — | degraded |
no shot | Senate committee text ↗ Senate Finance / Judiciary | — | — | Native text native | Public domain / CC0 | 5 / 1 / 4 | 2026-08-04 | live |
no shot | Epstein-Files (raw mirror index) ↗ yung-megafone + community | DS1DS2DS3DS4DS5+7 | — | No OCR — | None stated | · / · / 5 | — | live |
no shot | NARA / Presidential libraries ↗ National Archives | — | — | Mixed varies | Public domain / CC0 | 3 / 1 / 2 | — | live |
no shot | epstein (raw HF mirror) ↗ AdcloseNN (HF) | DS1DS2DS3DS4DS5+7 | — | No OCR — | None stated | · / 4 / 2 | — | live |
no shot | epstein-emails (Qwen VL) ↗ to-be (HF) | House NovEmails | — | Open VLM Qwen 2.5 VL 72B | None stated | 3 / 1 / 3 | — | live |
no shot | EpsteinFiles (Mistral OCR claim) ↗ vikash06 (HF) | FBI Vault | — | Commercial OCR Mistral OCR (claimed, unverifiable) | None stated | · / 0 / 1 | — | card-only |
How to read the ratings
Each source carries three 1–5 ratings from our census of 2026-08-28. They measure the source as a text provider, not the underlying documents.
- Fidelity —
- how trustworthy the OCR text is: engine quality, redaction handling, provenance. A source that deliberately rewrites text (for example, PII-redacted exports) scores below a verbatim engine.
- Coverage —
- how much of the known corpus the source covers. The denominator is the DOJ release plus the House estate pages.
- Usability —
- whether you can actually get and use the text: license, bulk access, structure, and whether rows map back to EFTA numbers or filenames.
Scale numbers are the maintainer's own claim unless we marked them verified against the files. Where the two censuses disagreed, we kept the figure we could check. "Undisclosed" engine means the maintainer never named it — not that there is no engine.
Cross-validation
Ratings describe sources; cross-validation tests them. We sample a few hundred pages that several sources have all OCR'd, align each pair's texts, and measure a normalized character error rate between them. We add two symbolic checks that need no judgment: whether digit runs (dates, amounts, EFTA stamps) survive, and whether the expected stamp regexes still match. Pairwise error is symmetric and reference-free: a high rate means the two engines disagree, and the heatmap shows who disagrees with whom.
We only believe a claimed problem when we can verify it independently — by checking a third source's take on the same page or by reading the page image itself. Findings that survive that check appear here; the rest stay out.
Current battery: 450 sampled pages in 4 strata, 24 pair-stratum rows scored, seed 42. Alignment on raw image basenames: House NOV/OCT filenames are shared exactly by marker md stems and greg (22,903 nov / 8,718 oct rows); teyler keys are 'IMAGES-<dir>-<STEM>.txt' (covers NOV 100%); jmail567 doc_id equals the OCT image stem (3,680 rows, all OCT); kabass HouseOversightEstate rows carry renumbered DOJ-OGR keys with no filename mapping, so they join via the HOUSE_OVERSIGHT_###### stamp found inside their own OCR text (6,794 unique stems; doc-level rows were cut to the '--- page N ---' segment containing the stem). DOJ joins on EFTA numbers: marker frontmatter eftaNumber vs ishumilin document_id vs kabass DataSet1 file_key vs jmail-doj doc_id prefix. Four batteries: nov (160 pages in 4 sources + 40 in 3), oct (80 in 4 + 20 in 3), doj (100 pages from the 3,145-doc 4-source intersection, photo-skewed) and doj-text (all 50 text-rich docs, marker ocrChars>=1000, in the same 4-source intersection). Normalization: lowercase, collapse whitespace, strip soft hyphens (U+00AD/U+2010); CER = rapidfuzz Levenshtein / max(len); digit Jaccard over multisets of digit runs >=3; stamps matched case-insensitively (EFTA\d{8} | HOUSE_OVERSIGHT_\d{6}). RNG seed 42; sampling code in /tmp/crossval.
Results of the 2026-08-28 battery — every finding below passed an independent check
- The estate-release engines agree closely. On the 200-page Nov-12 stratum, pairwise median character error runs 2.6–5.0% and digit runs survive at 0.95–0.98 Jaccard across Tesseract (teyler), Gemini 2.5 Flash Lite (kabasshouse), and the text this site serves.
- Provenance audit (verified by direct diff): the 31,621 estate-release pages this site serves carry the ep-nov-12.greg.technology mirror's OCR text. The marker|greg pair reads CER 0.000 because they are the same text, not because two engines agree. Our own marker-pdf OCR covers the other 14,961 ingested documents (DOJ, FOIA, and misc groups).
- One image-verified reversal: on EFTA00003047, a rotated photograph of an emergency-contact form, our marker output shatters the rotated lines into per-letter fragments while Reducto (jmail) reads the page cleanly. Rotation is a real marker weakness on photo-style pages.
- Photo pages measure differently: ishumilin stores image references instead of text on them, ishumilin and kabasshouse keep stamp-only text on 71–73% of the photo-skewed stratum, and jmail's DOJ drop carries VLM image descriptions rather than OCR there. A CER of 1.0 in this stratum means one side had no text — not that an engine failed.
- Known limits: ishumilin is page-level while the other sets are document-level, so the text-rich DOJ stratum mixes levels and its high error rates (0.46–0.82 mean) must not be read as engine quality. The official NOV TEXT layer was not fetched within the battery's time-box and is next in line.
What we hold
Mirrored copies behind this site: the full Jmail open-data parquet set, the ishumilin and kabasshouse Hugging Face corpora, the small specialist sets (svetfm's Textract FBI files, the teyler 20k lineage, LovenSar's GLM output, the 567-labs annotated family), rhowardstone's structured-data mirror, and the only surviving copy of the ep-nov-12.greg.technology OCR database. We also hold both House Oversight official containers — the NOV container includes its TEXT and NATIVES; the OCT container does not. Ask before redistributing any of these: several carry no license or a non-commercial one, and this page records that rather than deciding it.
Method and provenance
The census ran on 2026-08-28 against live sites, APIs (Hugging Face, CourtListener, DocumentCloud, Wayback), and the maintainer's own documentation. Every claim in the underlying research carries its source URL, and screenshots show each site as we captured it. The catalog regenerates fromdata/catalogs/ecosystem/ via scripts/build_ecosystem_catalog.py; the ratings methodology follows the fleet's controlled-prose rules for evidence grading. The engine provenance of our own served text is documented indocs/ocr-engine-provenance.md. Corrections and new sources are welcome — the EFTA number or filename is the universal key, so adding a source is usually just metadata.